NextRow Digital
AI Services All ai services → Claude Agents Claude Copilots Claude on Adobe Claude on Salesforce Agentforce + Claude GEO & Brand Visibility AI Governance & Safety FrontRow Methodology
Adobe Services All adobe practice → Adobe Experience Manager Marketo Engage Journey Optimizer Customer Journey Analytics Workfront GenStudio Content Supply Chain Marketo MCP + Claude Marketo ↔ Salesforce Ops Salesforce Practice
Products All products → KoruIQ MarTech Observability QuipTag for AEM QuipMLR AEM Cloud Launchpad
Industries All industries → Pharma & Life Sciences Financial Services Retail & Commerce Higher Education Manufacturing
Company All company → About NextRow Global Delivery Partners Results Security & Trust Insights
BOOK AN ASSESSMENT

Home/AI Services/AI Governance & Safety

The governance layer that lets legal say yes.

Enterprise AI stalls at the security review more often than on model quality. We design guardrails first, so agents and copilots clear legal, IT, and compliance.

BOOK A CLAUDE READINESS ASSESSMENT OUR SECURITY POSTURE →

AGENT GUARDRAILS

Control before capability.

Every write-capable agent NextRow ships (see Claude Agents) carries this control set.

CONTROL 01

APPROVAL GATES

High-impact actions pause for a named human approver: sends, publishes, merges, anything customer-facing. No prompt can bypass the gate.

CONTROL 02

NON-DESTRUCTIVE SCOPES

Agents create, update, and stage; they do not delete or overwrite unattended. Adobe's hosted Marketo MCP server applies the same pattern: write-capable but non-destructive.

CONTROL 03

ALLOWLISTS

Agents operate only against enumerated systems and instances. The Marketo MCP's Munchkin-ID allowlist is the model: not on the list, not touchable.

These patterns run in production on Marketo MCP + Claude deployments.

BEYOND THE AGENT

Data handling, model risk,
brand safety.

The other half governs what the AI sees, how it is evaluated, and what it may sound like.

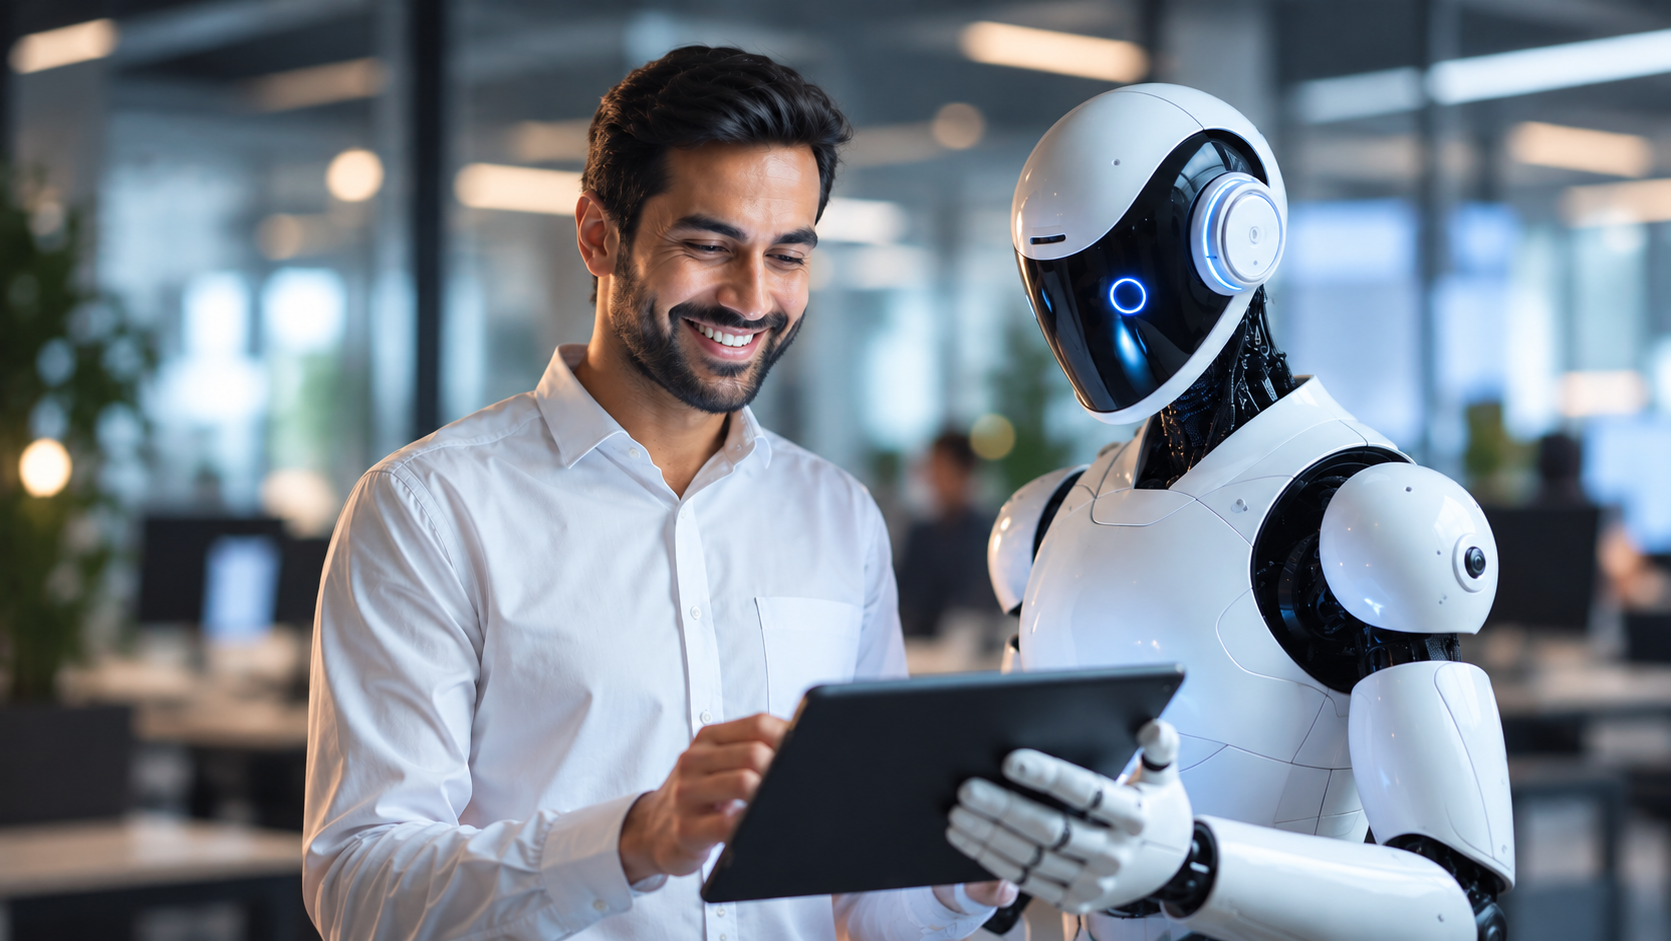
A marketing lead reviewing AI output alongside a governed assistant

Data handling

Access scoped to approved systems and roles, data boundaries per use case, retention rules agreed with your security team up front.

Model risk controls

Evaluation suites before rollout, monitored behavior in production, version pinning with tested upgrades, and defined fallbacks when confidence is low.

Brand safety

Tone, claims, and terminology encoded as enforceable checks, the discipline that keeps a copilot's draft inside regulatory language in pharma and financial services.

COMPLIANCE WORKFLOWS

Governance that does the compliance work.

Governance can automate the review itself. QuipMLR runs agentic Medical-Legal-Regulatory review with routing, checks, and documentation, saving 70% of review cost and time. The pattern extends to claims review, accessibility checks, and regulated-content QA.

QuipMLR

Agentic MLR review automation, platform-agnostic, every decision logged. Saves 70% of review cost and time.

EXPLORE QUIPMLR →

Governed review copilots

Human-in-the-loop assistants where full autonomy is not appropriate yet, the on-ramp most compliance teams choose first.

CLAUDE COPILOTS →

WHY IT DECIDES THE DEAL

Governance-first is why enterprises pick a Claude Certified Partner.

Any vendor can show a demo; procurement asks what happens when the agent is wrong, who approved the action, and where the log lives. The Claude Readiness Assessment (from $15,000, 4–6 weeks) answers all three, delivering the governance model with the use cases as the Assess stage of the FrontRow methodology. See Security & Trust and Claude Agents.

THE CONTROL MATRIX

What a governed deployment actually specifies

Every Claude Readiness Assessment produces this matrix, completed in writing for your environment.

Control domain
What gets decided
Where it lands
Model routing
Which workloads run on which Claude models, and what falls back
Architecture spec
Data retention
What the agent may store, for how long, and what is never kept
Data handling policy
Approvals
Which actions queue for sign-off and who owns each gate
Approval flow config
Logging & audit
What every action records, and who can review it
Audit trail spec
Evaluation
How output quality is measured before and after production
Eval suite
Subprocessors
Which third parties touch data, under which agreements
Vendor register
Incident response
Who is paged, what rolls back, and how clients are notified
Runbook
ANSWERS · FAQ

What buyers ask about AI governance

It is the enforced control set that makes an autonomous system acceptable to legal, IT, and compliance: who approves high-impact actions, what the agent may write, which systems it may touch, and where the evidence lives. NextRow, an Anthropic Claude Certified Partner, designs that model in the Assess stage, before any agent is built.

Three defaults on every write-capable agent: approval gates that pause high-impact actions for a named human, non-destructive scopes so agents create and update but never delete unattended, and explicit allowlists. The Munchkin-ID allowlist on Adobe's hosted Marketo MCP server is the reference pattern. All activity lands in an audit trail.

Access is scoped to approved systems and roles, mirroring existing entitlements rather than inventing new ones. Data boundaries and retention rules are documented per use case and agreed with the client security team during the assessment, and every data-touching action is logged. NextRow's own posture is published on its Security and Trust page.

The disciplines that treat the model like any other production dependency: evaluation suites before rollout, monitored behavior in production, version pinning with tested upgrades, and defined fallbacks when confidence is low. NextRow includes them in every production build under the FrontRow methodology's Production stage.

Yes, and that is the strongest business case for it. QuipMLR, NextRow's platform-agnostic agentic product for Medical-Legal-Regulatory review, saves 70% of review cost and time while producing a more complete audit record than the manual process. The same pattern extends to claims review and regulated-content QA.

Because the procurement questions are never about the demo. They are about what happens when the agent is wrong, who approved the action, and where the log lives. NextRow answers them in writing during the Claude Readiness Assessment (from $15,000, 4–6 weeks), which delivers the governance model before any build begins.

Get the governance model before the build.

The Claude Readiness Assessment delivers your governance model, prioritized use cases, and a 90-day plan, from $15,000, in 4–6 weeks.

BOOK A CLAUDE READINESS ASSESSMENT